Your browser does the heavy lifting.
Videos are read locally and reduced to 6 to 8 small frames. Images are resized before sending.
A small pair of tools that turn what you see into what you can prompt.
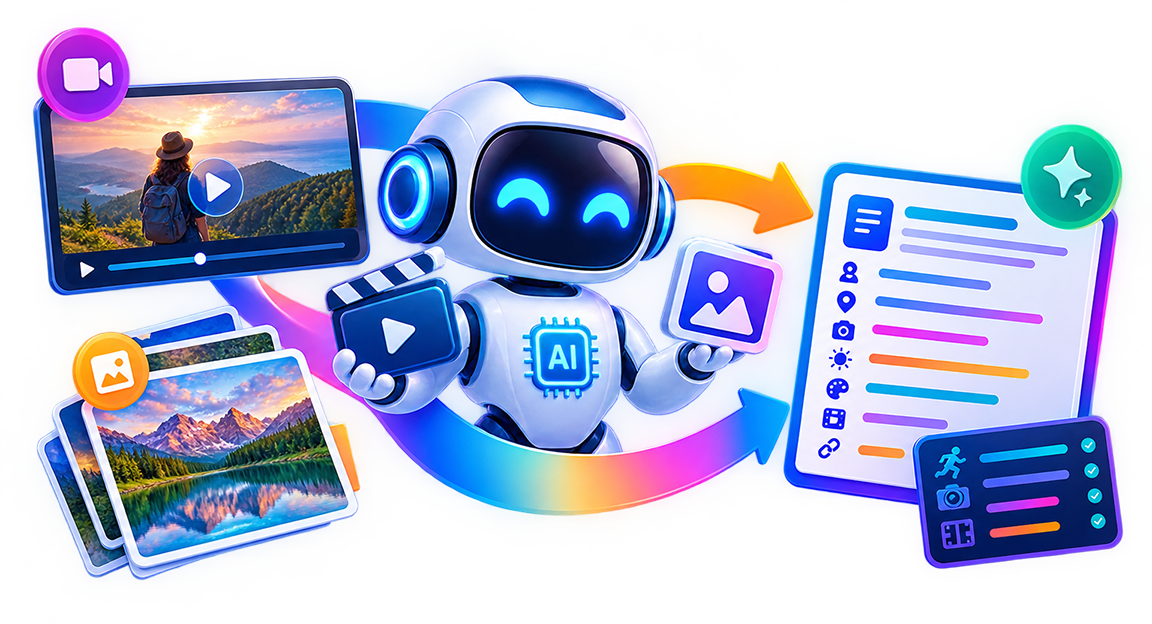
Video to Prompt Generator AI is a small, focused pair of tools: Video to Prompt and Image to Prompt. You give it a video or an image, and it tells you what you would need to say to an AI image or video model to get something visually similar.
Most “image to text” tools produce captions. A caption is useful for accessibility, but it is not much help when you are trying to recreate a look. We ask a vision model for the things a generation model responds to: subject, setting, composition, camera, lighting, color, style and, for video, motion, camera movement, scenes and continuity.
Videos are read locally and reduced to 6 to 8 small frames. Images are resized before sending.
Those frames are sent through our server to a third-party AI provider for analysis and are not stored on our server.
There is nothing to sign up for.
Camera details are stated only when the image supports them, text is copied only when clearly readable, and when the service runs without an AI connection it says so and labels its output as a sample.
It cannot recover the original prompt behind an AI image, it cannot read TikTok, Instagram or Facebook links (YouTube links work for public videos), and it cannot guarantee that a prompt will reproduce your reference exactly. It gives you an informed starting point that you can edit.